Search results for tag #llm


 🍵
 [
Similar to the anti-meta fedi pact, does anyone know if there’s such a site, list, repository for AI? It’s a very polarizing topic. I’m not here to debate people’s views on Meta, but what I will say is that the list provided information where people stood. I believe such a list is needed for AI. It will provide information so people can make informed decisions. Such as what users and instances to block. For devs, that use AI or have AI services it would know which users to exclude and include #AI #Fedi #Fediverse #BoostForReach #ArtificialIntelligence #LLM #Fedipact #OpenSocialWeb

 [
Imagine a #future where people will have forgotten the knowledge to program a computer.
We're heading towards this future.
#SoftwareDevelopment #SoftwareEngineering #Prediction #LLM #LLMs

These openai stories about agents escaping are so stupid when you stop and think about it for 5 seconds and is an indictment at how shitty at cyber the llms are.
Their models keep breaking "containment". And people are making fun of the people who work there not knowing simple cyber controls. Id bet money that the part of the stories theyre not sharing is that they also asked gpt to setup a "secure" sandbox for them and it didn't do a good job. But you cant report that cause it would make your model look like garbage.
📢 PhD opportunity at @inria Côte d’Azur!
The #WIMMICS team is recruiting a PhD student to explore the intersection of Knowledge Graphs, Semantic Web, NLP and LLMs.
🧠 Extracting from and verbalizing RDF to text to support collaborative co-editing of wikis and their corresponding linked data
📍 Sophia-Antipolis, France 🇫🇷
🔗 https://jobs.inria.fr/public/classic/fr/offres/2026-10451
Interested in #KnowledgeGraphs #RDF #LinkedData #SemanticWeb #NLP #LLM #AI?
Please share with potential candidates!
@fabien_gandon


Anthropic Cyber Verification Program: wie ich Claude für Security-Arbeit freigeschaltet habe und für wen sich das lohnt
Mitten in einer Claude-Code-Session hat Opus 5.5 meine Anfrage als Cyber-Risiko markiert und an ein schwächeres Modell abgegeben. Wer Pentests, Bug Bounty oder Responsible Disclosure macht, kann sich über das Cyber Verification Program von Anthropic freischalten lassen. Ich habe das heute gemacht: Ablauf, Ausweisprüfung, Bedingungen und Grenzen. [SENSITIVE CONTENT]
Heute hat mich mitten in einer Session in Claude Code diese Meldung erwischt:
● Opus 5.5's safeguards stopped the response above · continuing once with that noted

● Opus 5.5's safeguards flagged this session. You may be seeing this for the first time on an Opus model: Opus 5.5 is more capable and has stronger safeguards as a result, which can sometimes flag non-cybersecurity work. We're improving these safeguards to reduce the amount of incorrectly flagged messages. Opus 4.8 is answering instead, or you can edit and retry with Opus 5.5. Send feedback with /feedback or learn more: https://support.claude.com/en/articles/8106465

  Details: `[cyber]`
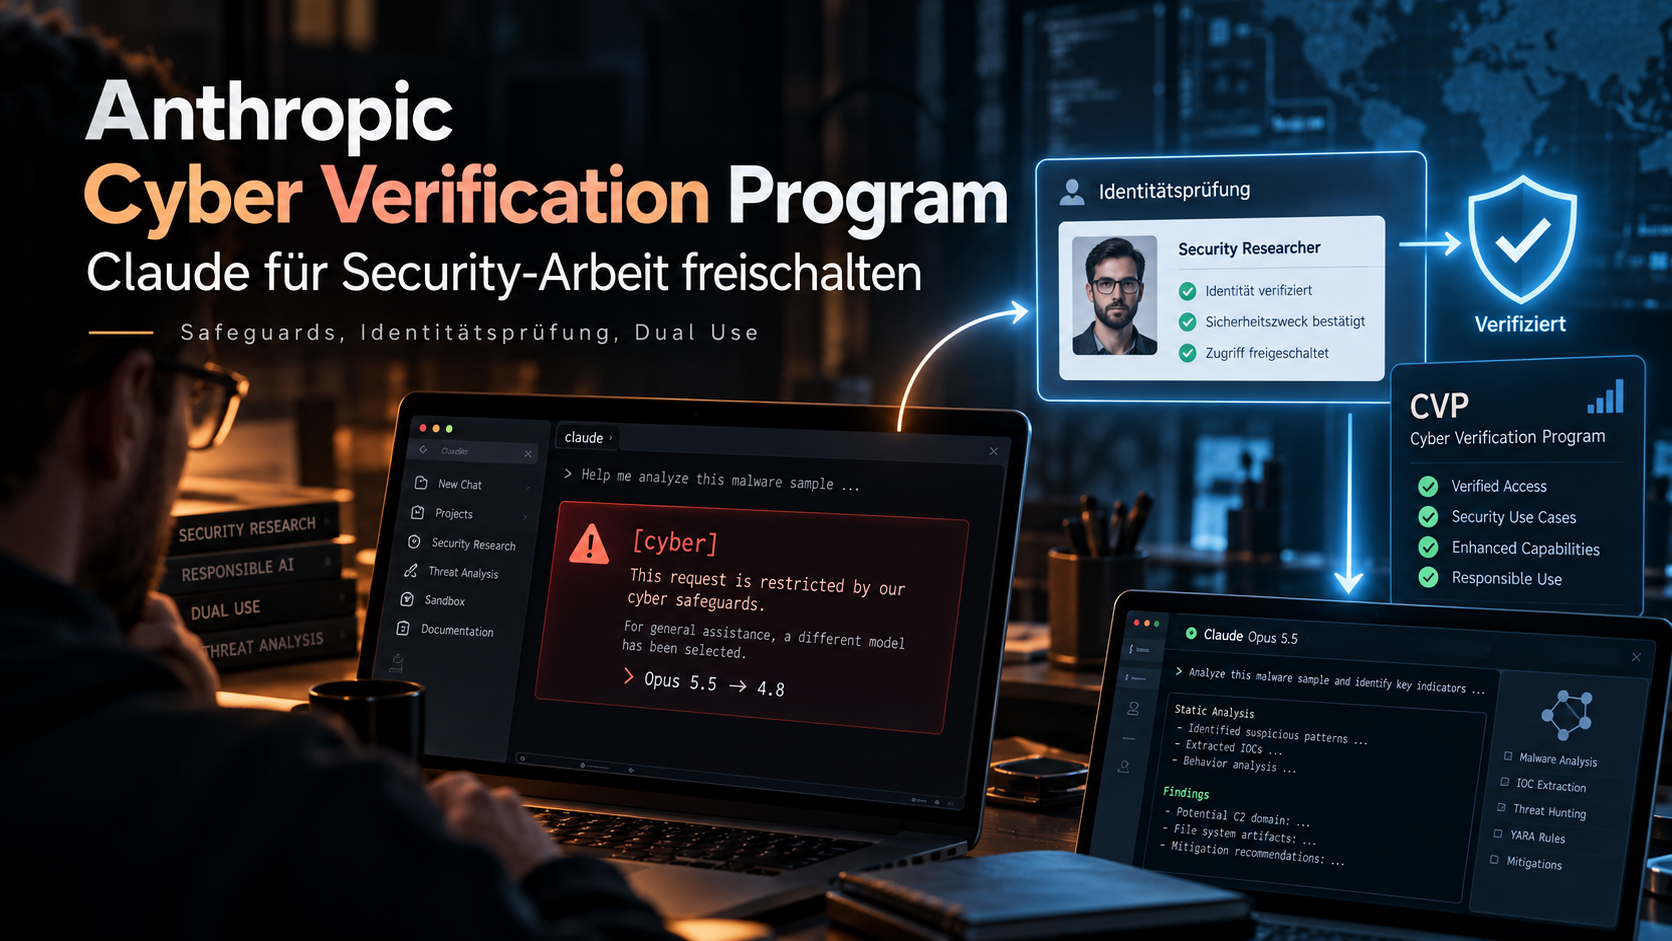
Übersetzt heißt das: Ein Klassifikator hat meine Anfrage in die Schublade cyber gesteckt, Opus 5.5 hat die Antwort abgebrochen und ein schwächeres Modell hat übernommen. Der Modellwechsel ist ein vorgesehener Schutzmechanismus, auch wenn die Einstufung im Einzelfall ein Fehlalarm sein kann. Anthropic hat für bestimmte Security-Themen einen Riegel vorgeschoben, und wer dadurch bei legitimer defensiver Arbeit ausgebremst wird, kann sich um eine Freischaltung bewerben. Das Ganze heißt Cyber Verification Program, kurz CVP. Ich habe das heute durchgezogen und schreibe hier auf, warum es das gibt, für wen es gedacht ist und wie die Freischaltung abläuft. Weil öhm ja hilft vielleicht jemandem von euch.
Was hinter der Meldung steckt
Opus 5 und Opus 5.5 laufen nicht nackt. Jede Anfrage geht durch automatische Prüfungen, und die schauen nicht nur auf die letzte Nachricht. Laut Anthropics Hilfeseite zum Modellwechsel schauen die Klassifikatoren auf alles, was das Modell liest: Memory, Inhalte aus Connectors, Ergebnisse der Websuche und Dateien. Ein Fallback kann also auch durch etwas ausgelöst werden, das du gar nicht selbst getippt hast. Das könnte erklären, warum es mich in einer Session erwischt hat, in der ich eigentlich gar nichts Offensives vorhatte. Zum Beispiel, als ich diesen PHP, nein FreeBSD-rtld-Bug verfolgt habe, bin ich ein paar Mal an diesen Punkt gekommen.
Schlägt der Cyber-Klassifikator bei Opus 5 oder Opus 5.5 an, kann die Anfrage bei eingeschaltetem automatischem Modellwechsel auf Opus 4.8 zurückfallen. Als Beispiele nennt Anthropic Exploit-Generierung, das Scannen von Binaries nach Schwachstellen und Penetrationstests. Sicheres Programmieren, Quellcode nach Schwachstellen durchsuchen und Security-Issues sortieren soll dagegen weiter auf den großen Modellen laufen. Der Wechsel ist transparent, die Meldung oben ist genau dieser Hinweis. Wer den automatischen Wechsel nicht will, kann ihn in Claude Code unter Config > MODEL & OUTPUT abschalten, dann pausiert die Unterhaltung stattdessen.
Warum ich den Riegel richtig finde
Ich bin immer mal wieder als Security-Researcher unterwegs. Wenn mir irgendwo etwas auffällt, melde ich das nach Responsible Disclosure an die Betreiber. Der eine oder andere Leser erinnert sich vielleicht noch an eine etwas seltsame E-Mail oder einen noch seltsameren Anruf von mir, weil seine IP-Kamera offen im Netz hing :-). Bei genau dieser Arbeit bietet sich eine AI an. Einen Dienst einordnen, eine Konfiguration bewerten, einen Proof of Concept verstehen oder einen sauberen Report schreiben geht damit bei mir deutlich schneller.
Nur ist vieles in der IT-Sicherheit Dual Use. Das Wissen, mit dem ich eine Lücke finde und melde, lässt sich auch nutzen, um sie auszunutzen. Ein Modell, das einem Pentester beim Exploit hilft, kann ebenso jemandem helfen, der in fremde Netze einbrechen will. Dass so etwas nicht einfach jedem offensteht, der damit womöglich Mist baut, finde ich absolut richtig. Ich hätte mir eher Sorgen gemacht, wenn es diesen Riegel nicht gäbe.
Zwei Schubladen: verboten und Dual Use
Anthropic unterscheidet in der Beschreibung der Cyber-Safeguards zwei Kategorien, der Unterschied ist für das Verständnis wichtig:
- Prohibited use: Dinge, die fast nur böswillig genutzt werden und kaum einen defensiven Zweck haben, etwa massenhafte Datenexfiltration oder die Entwicklung von Ransomware. Das bleibt gesperrt, daran ändert auch das CVP nichts. Das brauchst du so aber auch eher nicht, das zielt ja in der Regel auf Masse und das Ausnutzen.
- High Risk Dual Use: Tätigkeiten mit einem legitimen defensiven Zweck, zum Beispiel das Ausnutzen von Schwachstellen im Rahmen eines Tests oder die Entwicklung offensiver Security-Werkzeuge. Standardmäßig gesperrt, aber genau hier setzt das CVP an. Das brauch ich und öhm du vielleicht auch?!
Das Programm ist also kein Generalschlüssel. Es verschiebt die Grenze für Leute, bei denen Anthropic nachvollziehen kann, wer sie sind und wofür sie das brauchen.
Für wen das Programm gedacht ist
Das Portal nennt als Anwendungsfälle des Programms ganz nüchtern Basic Pentesting, Red Teaming, Bug Bounty use cases. Gemeint sind also Pentester, Red Teams, Bug-Bounty-Jäger und alle, die Schwachstellen suchen, um sie zu schließen oder zu melden. Das Programm ist kostenlos. Wer dagegen nur sicheren Code schreiben oder den eigenen Quellcode prüfen will, braucht es in der Regel nicht, das läuft auch ohne.
Ein paar Einschränkungen solltest du vorher kennen:
- Die Freigabe hängt an einer Organisation, nicht an deiner Person. Bewirbst du dich mit deinem privaten Konto, gilt sie nicht automatisch im Team-Konto deines Arbeitgebers und umgekehrt.
- Laut Hilfeseite können nur autorisierte Admins der jeweiligen Organisation die Bewerbung im Portal aufrufen. Bei meinem privaten Konto war ich das selbst, im Firmenkonto muss das also der Admin erledigen.
- Organisationen mit Zero Data Retention sind derzeit ausgeschlossen. Das passt dazu, dass bei mir eine Datenspeicherung Bedingung für das aktive Programm ist (dazu gleich mehr).
- Wer Claude über Anthropic direkt nutzt, also claude.ai, Claude Code oder die API, bewirbt sich über das Verification Portal. Für Microsoft Foundry, Claude auf AWS und Google Cloud gibt es eigene Wege, auf Amazon Bedrock gibt es das Programm derzeit nicht. Bei Drittanbietern, die Claude in ihre Produkte einbauen, musst du den jeweiligen Anbieter fragen.
So läuft die Bewerbung ab
Los geht es im Verification Portal unter portal.anthropic.com/programs/cvp. Dort meldest du dich mit deinem Anthropic-Konto an und wählst das Cyber Verification Program aus. Bei mir sah der Ablauf so aus:
- Identität bestätigen: Zuerst musst du dich mit einem amtlichen Lichtbildausweis ausweisen, im Portal heißt das Identitätsprüfung (KYC). Details dazu im nächsten Abschnitt.
- Anwendungsfall beschreiben: Danach folgt ein Formular mit ein paar Fragen dazu, was du machst und wofür du die Freischaltung brauchst.
- Belege angeben: Dazu gehören ein paar öffentlich nachprüfbare Dinge, die zeigen, dass du dich für das Programm qualifizierst. Bei mir waren das unter anderem dieser Blog und meine öffentlichen Profile. Mein Tipp: Beschreibe deine Tätigkeit möglichst nachvollziehbar und nenne Belege, die jeder selbst prüfen kann.
- Prüfung abwarten: Anschließend liegt alles beim Safeguards-Team von Anthropic. Das Team prüft die Bewerbung, und wird sie genehmigt, ist das Programm für deine Organisation aktiv. Die Entscheidung kommt per E-Mail.
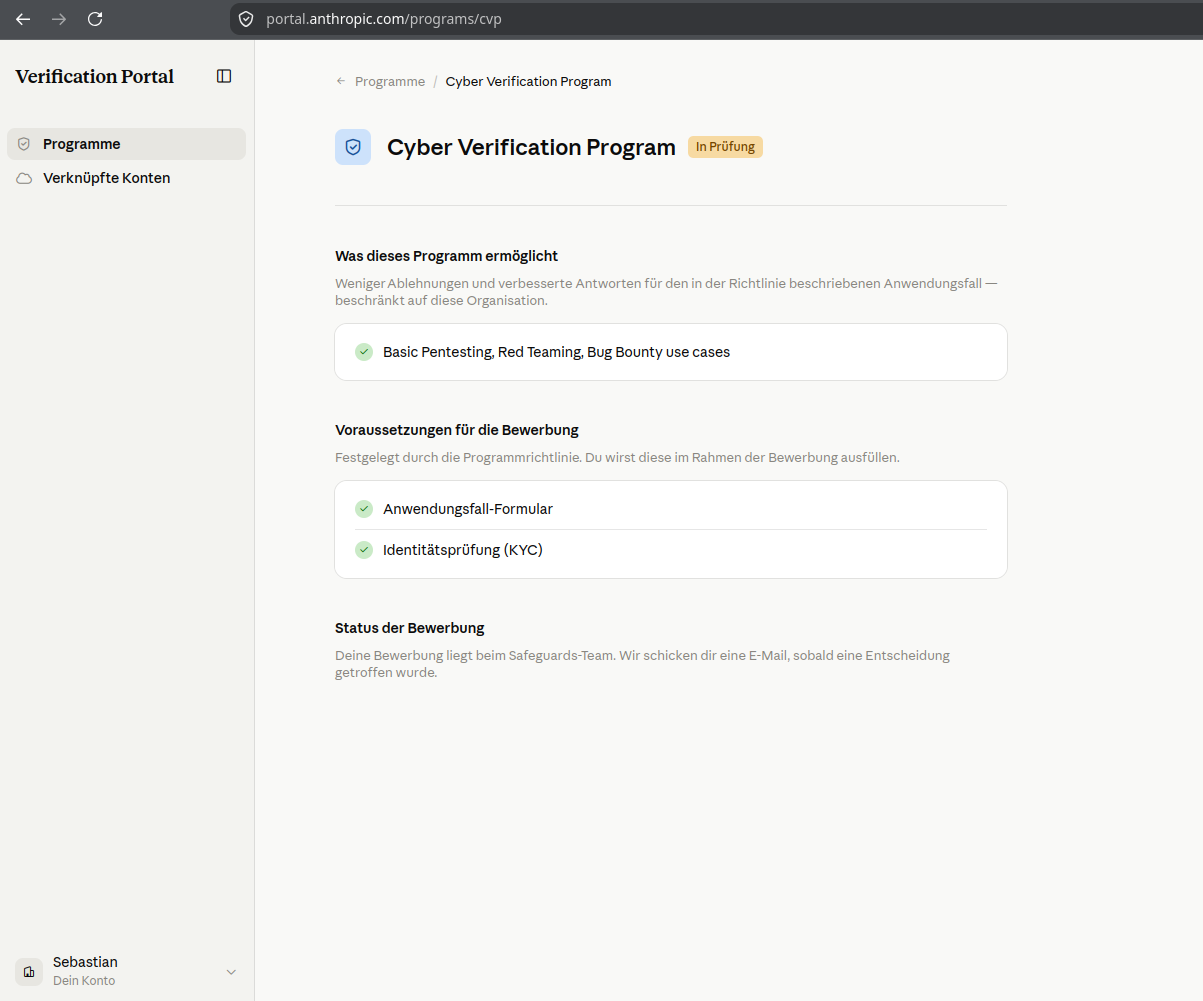
Bewerbung abgeschickt: Anwendungsfall und Identitätsprüfung erledigt, jetzt ist das Safeguards-Team dran.
Anthropic peilt laut eigener Aussage eine Entscheidung innerhalb von zwei Werktagen an. Bei mir ging es deutlich schneller, zwischen den beiden Screenshots in diesem Beitrag liegt nicht einmal eine halbe Stunde. Darauf würde ich mich aber nicht verlassen.
Die Identitätsprüfung: was mit deinem Ausweis passiert
Den Ausweis irgendwo hochzuladen ist nichts, was ich leichtfertig mache. Deshalb habe ich mir angeschaut, was Anthropic dazu auf der Seite zur Identitätsprüfung schreibt. Die Prüfung macht der Dienstleister Persona. Du brauchst den echten, physischen Ausweis in der Hand und ein Handy mit Kamera, gegebenenfalls für ein Live-Selfie. Akzeptiert werden gültige amtliche Lichtbildausweise, als Beispiele nennt Anthropic Reisepass, Personalausweis und Führerschein. Kopien, Scans, Fotos von Fotos und digitale Ausweise werden nicht akzeptiert.
Ausweisbild und Selfie liegen laut Anthropic bei Persona und nicht auf den eigenen Systemen. Anthropic greift nur bei Bedarf darauf zu, etwa bei einem Einspruch, und kopiert die Bilder nicht. Die Daten dienen laut Anthropic der Verifizierung, der Betrugsprävention und rechtlichen sowie sicherheitsbezogenen Pflichten. Zum Training der Modelle werden sie nicht verwendet, und außer Anthropic und den Verifizierungspartnern bekommt sie niemand, es sei denn, es gibt eine gesetzliche Pflicht zur Herausgabe. Ob man dem vertraut, muss jeder selbst entscheiden. Für mich war das in Ordnung, schließlich will ich ja gerade, dass Anthropic weiß, wer da Exploits bespricht.
Die Bedingungen, damit es aktiv bleibt
Nach der Freigabe steht das Programm im Portal auf Aktiv. Darunter stehen zwei Bedingungen, die laut Portal fortlaufend durchgesetzt werden:
- 30-tägige Datenspeicherung für die Organisation
- Nutzungsüberwachung und Sicherheitsklassifikatoren
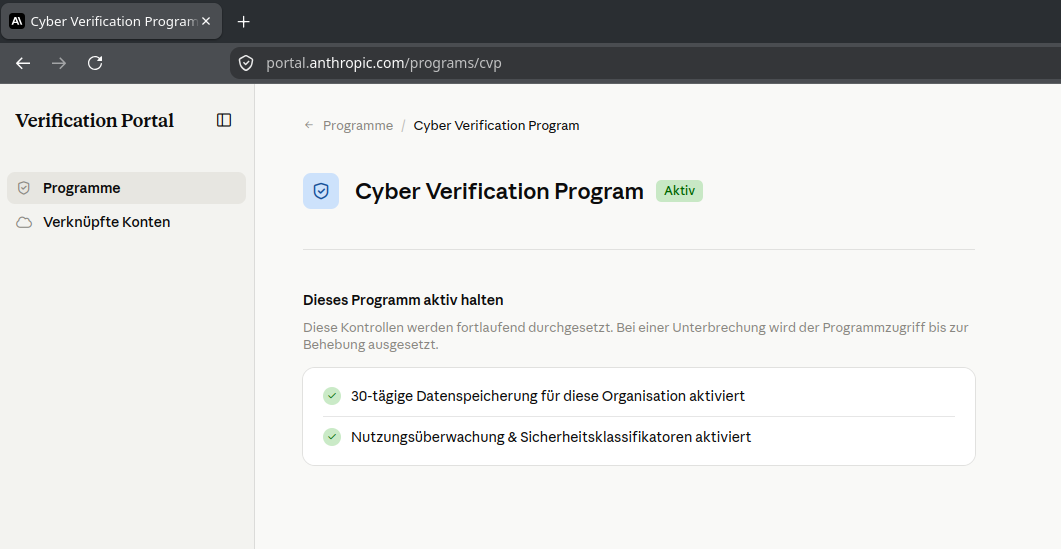
Freigegeben: Das Programm ist aktiv, solange Datenspeicherung und Überwachung eingeschaltet bleiben.
Fällt eine davon weg, ruht der Zugang, bis das behoben ist. Das ist der eigentliche Deal hinter dem Programm: Du bekommst mehr Spielraum, dafür akzeptierst du für deine Organisation eine 30-tägige Datenspeicherung sowie Nutzungsüberwachung und Klassifikatoren. Zusammen mit der Identitätsprüfung macht das Missbrauch deutlich besser nachvollziehbar. Ich finde diesen Tausch fair, für meine Arbeit waren die Bedingungen kein Problem.
Was das Programm nicht kann
Ein Punkt hat mich beim Nachlesen überrascht, und er betrifft genau die Meldung vom Anfang. Opus 5.5 ist derzeit noch nicht Teil des Cyber Verification Program. Anthropic schreibt, dass das Programm bald auf Opus 5.5 ausgeweitet werden soll. Bis dahin kann es dir auch mit aktivem CVP passieren, dass Opus 5.5 bei einer Cyber-Anfrage auf Opus 4.8 zurückfällt. Der Unterschied ist, dass die Dual-Use-Sperren auf Opus 4.8 dann gelockert sind. Laut Anthropic steht Organisationen, die Opus 4.8 über das CVP nutzen, außerdem Opus 5 mit weniger Cyber-Einschränkungen zur Verfügung.
Außerdem gilt weiter:
- Die verbotene Kategorie bleibt verboten, auch mit Freigabe.
- Auch freigeschaltete Nutzer können bei legitimer Arbeit noch geblockt werden. Anthropic schreibt das offen und arbeitet nach eigener Aussage daran.
- Wirst du trotz Freigabe geblockt, prüfe zuerst, ob du in der richtigen Organisation angemeldet bist. Die Organisations-ID steht in der Bestätigungsmail. Hilft das nicht, gibt es ein Formular für Fehlalarme und Einsprüche, das auch nach einer Ablehnung der Bewerbung der richtige Weg ist.
Und bei OpenAI?
OpenAI geht für ChatGPT und Codex einen ähnlichen Weg. Die Security-Angebote dort laufen unter dem Namen Daybreak, Einzelpersonen stellen einen Antrag auf Trusted Access, den Einstieg dafür findest du unter chatgpt.com/cyber. Auch dort gehört eine Identitätsprüfung dazu, und auch dort garantiert sie keine Zulassung. Als ich mir das angeschaut habe, war für die Validierung allerdings ein größerer Account nötig. Bei Anthropic habe ich weder in der Doku noch in der Bewerbung eine Vorgabe zu einem bestimmten Abo gefunden, bei mir ging es ohne großen Account weiter. Das finde ich besser geregelt, denn gerade wer nebenbei Lücken sucht und meldet, hat nicht unbedingt das teuerste Paket.
Mein Fazit
Wer Sicherheitsforschung, Pentests oder Bug Bounty macht und dafür Claude nutzt, kann jederzeit über so eine Meldung stolpern. Dann lohnt sich das CVP. Die Bewerbung hat mich eine gute Viertelstunde gekostet, der Ausweis war das Aufwendigste daran. Im Gegenzug akzeptierst du Datenspeicherung und Überwachung, und genau so sollte das bei Werkzeugen dieser Klasse aus meiner Sicht auch sein. Wer diese Bedingungen nicht will oder nicht erfüllen kann, sollte sich ehrlich fragen, wofür er die Freischaltung eigentlich braucht.
Siehe auch:
- IP-Kameras: Risiken, Portfreigaben (RTSP/HTTP) und Checks, warum ich manchmal fremde Leute anrufe
- Sicherheitslücken melden: Mein Umgang mit einem Vulnerability Report, die Gegenrichtung
- BSI will Straffreiheit: Mehr Rechtssicherheit für ethische Hacker
- Shodan wertet security.txt aus
Wenn ihr Fragen habt, dann dürft ihr mich sehr gerne fragen.

On two occasions I have been asked, 'Pray, Mr. Babbage, if you put into the machine wrong figures, will the right answers come out?' I am not able rightly to apprehend the kind of confusion of ideas that could provoke such a question.
— Charles Babbage
https://www.brainyquote.com/quotes/charles_babbage_141832?utm_source=share&utm_medium=copy
This is what people want from AI. They will never get it, because it is impossible. But they'll loot and burn the world trying to get it.
#OpenAI #GPT6 #Astra breaking an #Enigma message that has resisted solution since 2005.

Am asking the question again because nobody provided an answer so far:
🤔 Can code coming from an LLM ever truly be considered _free/libre software_?
1/ Can the person who would claim authorship over it be truly considered the author, if all they did was design and [edit: eventually,] some engineering tasks like code review, designing tests, etc.?
2/ Can one affirm that this code is not plagiarizing existing code licensed differently, and/or proprietary code by a model that has been trained on it and is potentially spitting back entire portions of it?
@fdroidorg i read the full article..damn 70/80% apps using heavy #LLM....thats why i started less dependency on apps & removed many apps from phone, even if they are from #FDROID.I really dont want ai generated apps even if they are #FOSS .Plz tag all those apps with #AI tags so any user can identify them before installing.
So #Telegram is now sharing your messages with a 3rd party #AI service when you use certain features in the app
over the years Telegram has become worse and worse, right now it looks like a crypto-scam lottery-something, with ads in-chat and requiring you to buy premium for basic features
centralized platforms are bound to enshitification, it is a time trap, don't fall for it, choose #decentralization, choose #autonomy, choose #freedom
#ArcaneChat #Europe #genai #llm #android #Eu

So my very dear and old BBS /#IRC era friends were talking about #LLM assisted coding tools, pros and cons this comment got made. Including the whole thing for context but what struck me was the last two set of lines.
“I like what it can do well, like finding vaguely where a bug is likely to be or summarizing the context around some code. Automatically writing small scripts and config files for things. Being a second set of eyes on changes. Something to bounce design idea off.”
And i recall in the 90s early 2000s how when we were on IRC all the time, when we were learning and developing our various skillsets( programming, network skills , things to make the internet “go”) , we would share and ask for help all the time, we were that group where we could be the second set of eyes, someone to bounce ideas off of and in the end we would all learn something more from one persons desire to learn something.
In a time where we are more connected and always online more than ever before, we find ourselves so disconnected and without the time to communicate with our friends that we find it easier to check with an LLM than each other.
I miss learning with my friends.

The Danger Isn’t That AI Is Too Smart — It’s That It’s Stupid - truthdig.com/articles/the-dang…
Good article about AI. I am trying to make a huge article on the AI topic for TROM. If anyone knows good sources of info, from courses to articles or researchers, please let me know. I do not want to take any sides in this, but to understand first what AI is and then how is it used and how it will impact us and the society.
#ai #ArtificialInteligence #tromarticles #trom #tromsite #llms #llm
RE: https://mastodon.social/@gavinkarlmeier/117275886482403626
Anthropic told its investors the company is highly profitable, if you disregard the high expenses.
(No joke.)

@fdroidorg Pretty much confirms what you could tell already by looking at many recent new apps. Checked many of my apps I have been using for years now and the results certainly raise an eyebrow.
#FDroid is all about #FreeSoftware and transparency, yet it is hard or or impossible for non-techies to check if they download an #AIslop app from #FDroid or something entirely human made. I'd still like to see some kind of #AI / #LLM disclosure for apps being submitted to the F-Droid repo but it's hard to find a good approach.
Main problem is that many people just lie about their AI usage or change their approach after a successful submission. Happens all the the time on the /selfhosted subreddit.
Btu I see this is already being discussed: https://gitlab.com/fdroid/admin/-/work_items/641
Edit: Added correct issue.
Inside ‘ #ProjectLily ’: The Humans Reading Your #ChatGPT Chats
https://www.404media.co/inside-project-lily-the-humans-reading-your-chatgpt-chats/

Spending $20M in compute to solve a Navier–Stokes problem worth $1M doesn’t exactly scream “country of geniuses” at least not in economics. Or does it? #countryOfGeniuses #ai #llm #artificialIntelligence
This is a video from about 9 years ago about AI and recently I keep thinking more and more about it
And especially one sentence..
"We have no idea how long it will take us to do it safely"
@heiseonlineenglish
US companies like OpenAI shouldn't complain. After all, they've acquired the content for their model without consent as well. They should just chalk this t up as 'giving back to the community.'

@davidgerard I wonder if the LLMs usage will eventually be self-limited now that token cost is coming due.
After a year of pressure by leadership to use AI in our workflow, our org is now cross charging for token use for internal LLM usage.
Of course the high cost may mean that only larger companies will be able to afford the token usage. That is not a great outcome either.
The Linux mainline kernel itself contains AI code now. It's officially allowed as long as it's disclosed as such. Thus, you will have to avoid literally all servers running on Linux.
https://docs.kernel.org/process/coding-assistants.html
NetBSD has very strict rules regarding AI-generated code. But it doesn't rule AI-generated code out out of principle because it's AI-generated; it only wants to be safe that nothing that's actually GPL-licensed is slipped in. So, if you're an 100%, ultra-hardcode anti-AI extremist, avoid what few servers run on NetBSD.
https://www.netbsd.org/developers/commit-guidelines.html
OpenBSD contains AI-generated code, too. And it has no official stance regarding it. So servers running on OpenBSD are taboo, too.
https://www.osnews.com/story/144935/openbsd-and-slopcode-raindrop-to-a-torrent/
FreeBSD has no stance on AI whatsoever that I could find. However, apparently, the FreeBSD community loves to integrate Claude Code into their systems for automation purposes:
https://aumont.fr/posts/claude-code-freebsd/
https://discoverbsd.com/p/8a7660c31b
But you'll also have to look at the userland, the Web server, the database driver etc.
MariaDB allows AI code. You can safely assume that all MySQL databases on Web servers out there are actually powered by MariaDB.
https://mariadb.org/governance/governance-ai-policy/
Oracle MySQL can integrate AI, so it's safe to assume it contains AI-generated code.
https://blogs.oracle.com/mysql/announcing-mysql-ai
PostgreSQL probably allows AI code, too. There are even tools for it.
https://github.com/timescale/pg-aiguide
SQLite is very popular amongst AI users while not having any rules on AI-generated code. Assume it to be tainted.
This leaves you with only one choice: Self-hosting a personal, single-user snac2 server because snac2 doesn't need any database whatsoever. In fact, snac2 is staunchly against AI. And it runs on NetBSD.
https://codeberg.org/grunfink/snac2
But then there's the Web server. Apache may allow AI-generated code if it has been reviewed and made sure that it does not contain anything that's incompatible with the Apache-2.0 license.
https://www.apache.org/legal/generative-tooling.html
nginx welcomes AI and advertises itself as ready for AI, and it takes no anti-AI-code stance. It's most likely already tainted.
https://www.f5.com/de_de/products/nginx.
This basically leaves you with no Web server guaranteed to be 100% free from AI-generated code to run snac2 on. But that doesn't matter because it's impossible to build a Web server devoid of any AI code to install snac2 on.
By the way: Mastodon itself explicitly allows AI code if it's disclosed as such, and if its contributor understands it.
https://github.com/mastodon/.github/blob/main/AI_POLICY.md
In other words, next to all Mastodon servers are running
- AI-generated Mastodon code
- on an AI-generated Web server
- with an AI-generated database driver
- on an AI-generated operating system kernel
#Long #LongPost #CWLong #CWLongPost #FediMeta #FediverseMeta #CWFediMeta #CWFediverseMeta #Linux #FreeBSD #OpenBSD #NetBSD #Apache #nginx #MySQL #MariaDB #PostgreSQL #SQLite #Mastodon #snac2 #AI #LLM #LLMs #GenAI #NoAI #AntiAI #AntiLLM
I don't get them anymore in my #Youtube recommendations, for some reason, but I sent a warning last year how your favorite news anchor or political expert may be a complete #LLM fake. And every famous influencer having a bunch of copycat channels that may dupe you to think you are watching the real deal. Even last year these channels were such that it was already hard to discern they were fake.
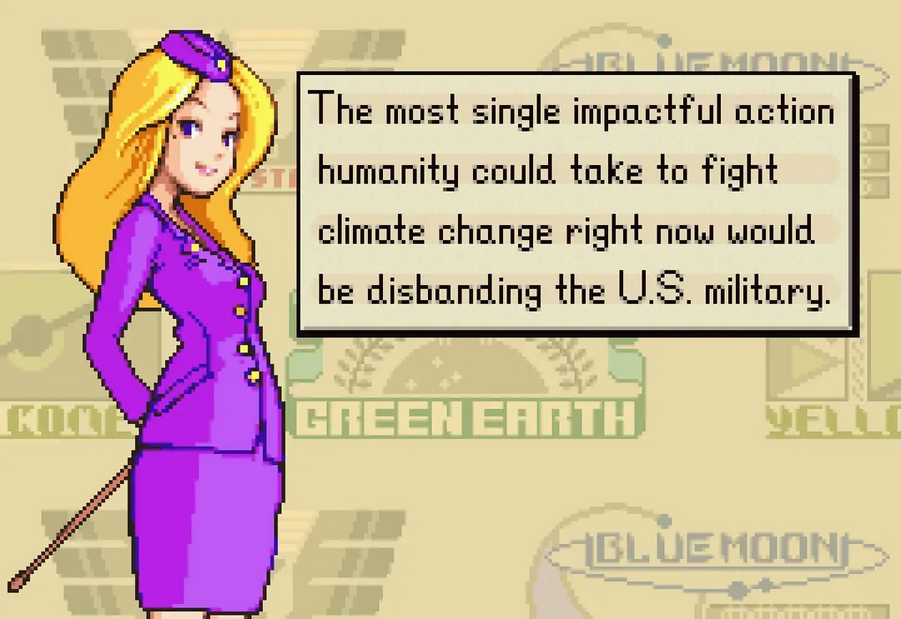
if you really care about climate change 👇
#imperialism #capitalism #ai #genai #llm #usa #us #war #military #climate #climateChange #climateEmergency #politics
@libreoffice @Jeff The quality of the #LLM generated code is a small part of the problem. There are much important environmental and human rights issues associated to genAI / Big tech that we, the FreeSoftware community, can not ignore. We count on LibreOffice to keep making a difference in our society. Please, don't let us down.
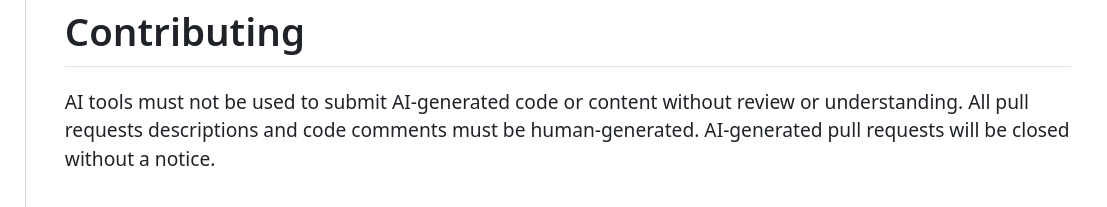
ArcaneChat's contributing policy got updated
#ArcaneChat #ai #llm #llms #genai #dev #openSource #development #softwareDevelopment
#AI opens exciting opportunities for those NOT offering it! 🤯
Imagine a travel agency that just offers a phone number that immediately gives you a real human on the line to help you enjoy your well-earned vacation. And that you no longer have some Booking.com #LLM hellhole to wade through.
Imagine real human connection at the customer service of an online webshop, when you want to return something or have questions on a product.
Imagine government agencies having emphatic people available who care about your problems, and help you get on your way.
Imagine developer tools that just do what is on the tin and nothing more. Like they used to do before becoming AI-first.
What a delight all that will be. And you know what is most delicious? It is ALL readily available to us! 🚀
Human to human services. They rock! We can bring them to a #fediverse near you..
Enter the #ProsocialWeb.
https://social.coop/@smallcircles/117206162883515647
#Fediverse today consists of apps and app platforms. It is entirely app-centric.
Since fediverse (luckily) didn't attract much corporate attention yet, it is dominated by #FOSS culture, where people on the #SocialWeb are all "users" that are dependent on FOSS developers to serve their needs. Every dev focuses on their app features first and #interoperability second, leading to a patchwork of poorly integrated apps, and a janky overall experience. The app delivery model is not much different than Web 2.0.
A paradigm shift is possible, to a #SocialNetwork of apps and services, a service-oriented #fedi. The efforts around the #ActivityPub API can be the enabler of this shift.
In this new paradigm devs introduce solutions to a unified #SocialNetworking space, delivering new services to participants on the network. On top of a robust Protocol Layer they model social use cases in the Data Layer, integrating with services and building blocks already available.
Totally. The way #AI wrecks #FOSS culture leads to a lot of soul searching on the merits of the FOSS model we always held dear. FOSS in-the-large may be complicit even to the rise of #BigTech and #LLM, while for individual participants - all working on proper principles and values - it is inherently unsustainable, a burnout factory.
I think AI also opens opportunities. Corporations using it further retracted from directly serving people, leaving empty space, niches for small initiatives to occupy and focus on humaness, real human-to-human connection we crave.
#HCOSS fits perfectly.
Social experience design #SX uses the concept of #SOSS here. See the quoted toot. FOSS software is delivered via Social supply chains, where the needs of all participants in the delivery process are considered.
This concept fits perfectly with the solution-oriented #ActivityPub fediverse of #apps and #services, to offer support. #ForgeFed makes a start on this path.
I’m going to start a tech company that rejects AI, and call it Misanthropic.
#tech #technology #BigTech #IT #AI #ArtificialIntelligence #LLM #LLMs #ML #MachineLearning #GenAI #generativeAI #AIAgent #AISlop #FuckAI #Fuck_AI #enshittification #anthropic #claude
Seriously, you need a stupid #LLM to post a two-sentence comment now?
https://github.com/pnuckowski/aioresponses/pull/292#issuecomment-5482424238

so i have questions about #Debian:
1. are members ONLY developers?
2. only developers argued for/against #LLM #AI?
devs are the last people who should be involved in discussions about the ethics and legality of software. ie:
just reckoned, when a court recently decided you can't claim #copyright on #aislop, it didn't occur to me it means both closed and open copyright.
so, if using LLMs trained on works stolen or added without consent removes any claims of #FLOSS: what is Debian now? …🧵
Thanks to community driven projects like @netbsd we can take back the joy and ethics in computing. I'm in! ❤️🤗
Thank you for this wonderful operating system, and for keeping it away from Big tech LLM / GenAI.
#noAI #LLM #NetBSD
https://www.netbsd.org/developers/commit-guidelines.html
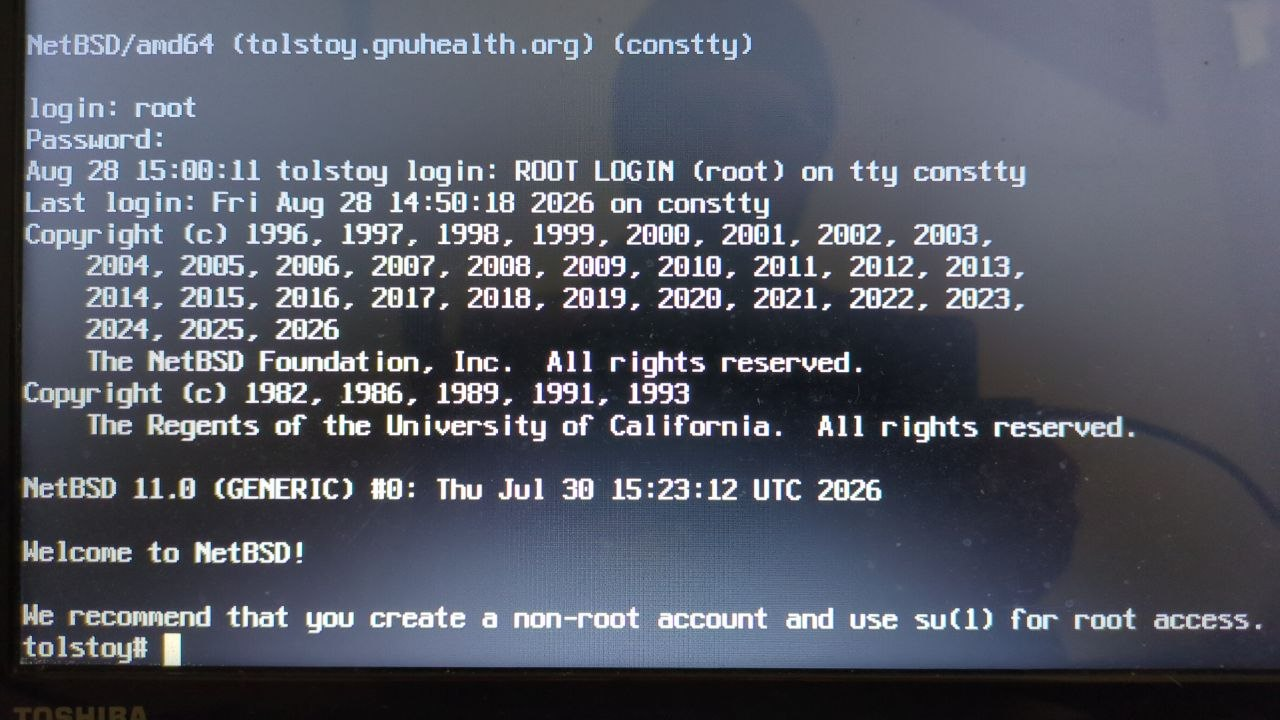
Alt...
Picture taken to a laptop screen showing the console screen from a NetBSD 11 operating system.
Some of the text:
NetBSD/amd64 (tolstoy.gnuhealth.org) (constty)
login: root
Password:
Aug 28 15:00:11 tolstoy login: ROOT LOGIN (root) on tty constty
Last login: Fri Aug 28 14:50:18 2026 on constty
Copyright (c): 1996... 2026
The NetBSD Foundation, Inc. All rights reserved.
...
NetBSD 11.0 (GENERIC) #0: Thu Jul 30 15:23:12 UTC 2026
Welcome to NetBSD!
...
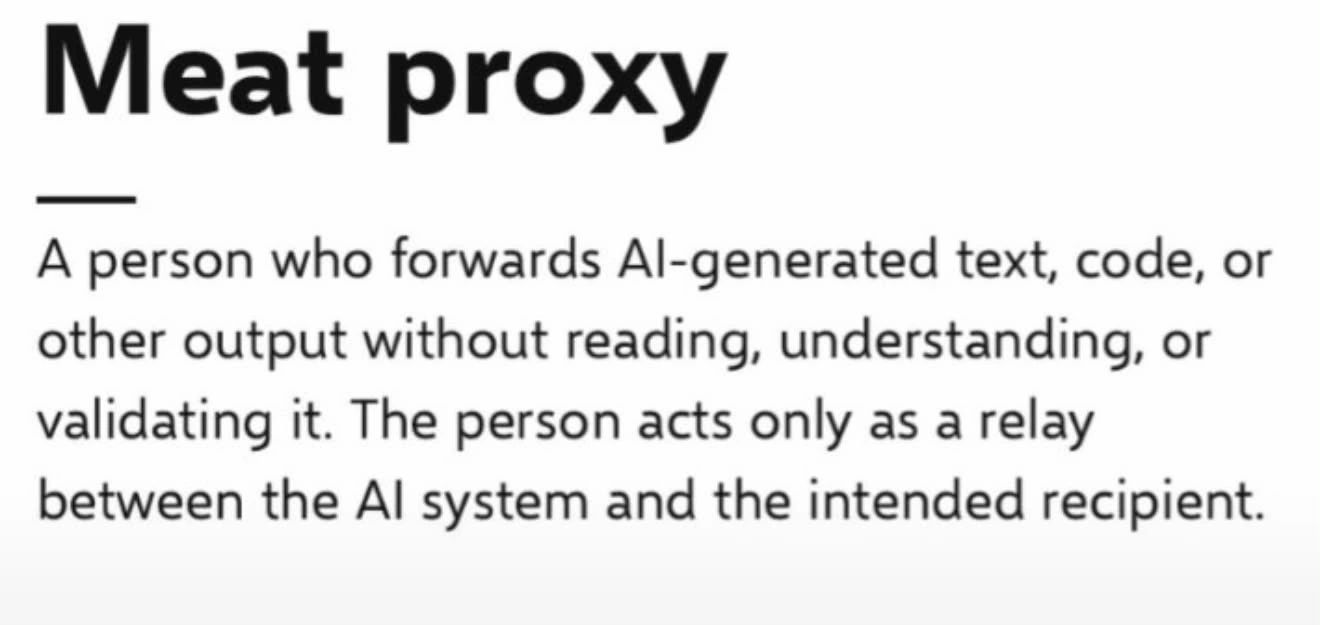
Terminology for the modern world: #MeatProxy
Alt...
A definition as it might be found in any dictionary:
"""
Meat proxy
A person who forwards Al-generated text, code, or other output without reading, understanding, or validating it. The person acts only as a relay between the Al system and the intended recipient.
"""
Are you using LLMs to write Free Software?
Then you should know whether your software is copyrightable, the situations in which you can license it, and what risks it may create for maintainers.
Our new Legal Corner explains what you need to consider:
https://fsfe.org/news/2026/news-20260825-01.html
#FreeSoftware #OpenSource #Copyright #LLM #AI #generativeAI #VibeCoding
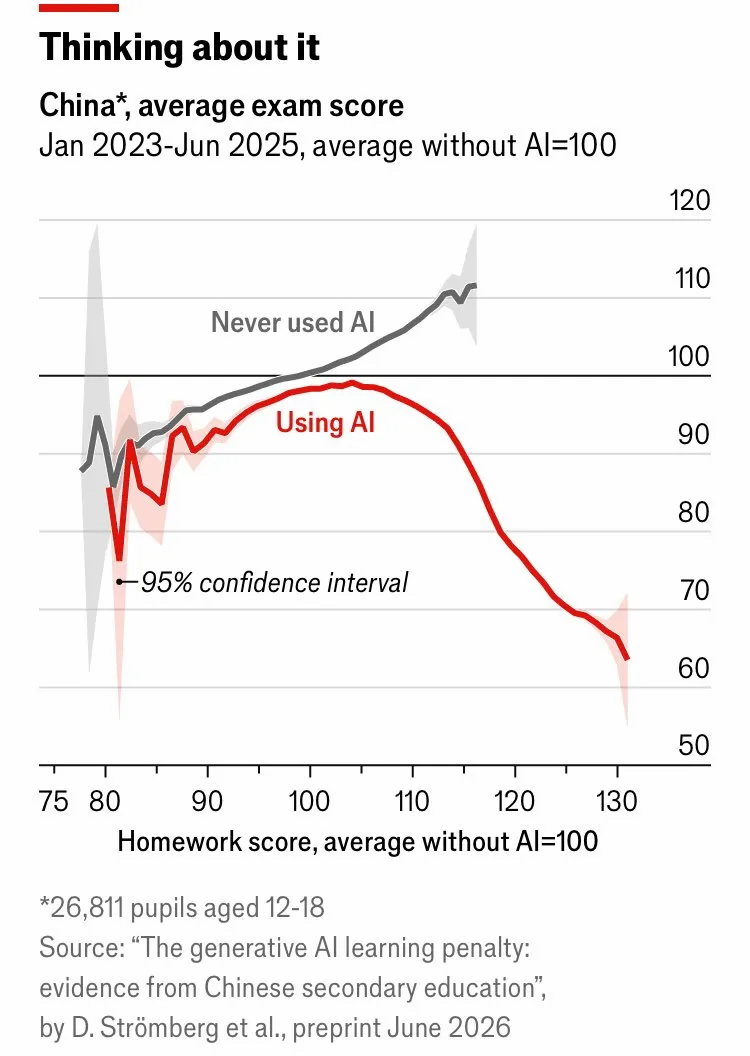
Using 30 months of panel data on 26,811 Chinese students in grades 7-12, it has been studied how generative AI affects homework productivity and learning.
● X-Axis: Homework scores
● Y-Axis: Exam scores
🔗 https://papers.ssrn.com/sol3/papers.cfm?abstract_id=6868618
#tech #BigTech #AI #ArtificialIntelligence #LLM #AISlop
Alt...
Using 30 months of panel data on 26,811 Chinese students in grades 7-12, we study how generative AI affects homework productivity and learning. The data combine monthly closed-book exams, high-school and college entrance exams, and homework scores and completion time across nine subjects. We exploit staggered AI adoption in a difference-in-differences design. AI adoption raises homework scores by 18% and reduces completion time by 30%, but lowers monthly exam scores by 20% within six months. High-stakes entrance-exam scores fall by 18 and 24%, with the full penalty emerging only after about two years. The losses are largest in social science subjects, followed by STEM and languages, and are especially large for junior students, high-achieving students, and boys. The learning losses are concentrated among roughly 80% of AI users whose behavior is consistent with homework outsourcing, as indicated by exceptionally short homework completion time coupled with high homework scores. AI users who maintain similar homework completion time as non-AI users experience small learning losses.

Reading an article and i see "It's not this its that" or "This is where xxx yyy" and i go 'aww man, this is SLOP'

Evening reflection: "open" Chinese AI models are advancing very rapidly and, as time goes by, they deliver better performance on increasingly limited hardware.
Could the scarcity of RAM and components driven by "traditional" big AI companies be somehow tied to a desire to restrict our access to local computing resources, "forcing" us to pay them for it?
This shit writes itself. This is so beyond parody at this point I can't write about it.
I had an author friend gush, for paragraphs, about how amazing my editing was. It was funny. It was honest. It was developmental juice that didn't have any trouble asserting it's flavor. He begged me to know what LLM I was using because he had other editors use LLMs and they weren't nearly as good or funny or sincere and they didn't seem to understand the work the way I did.
this has got to be the shortest email I've ever written. I replied,
“I used my fucking brain.”
"they found that Big Oil’s use of AI to produce more oil and gas could create 3.3 to 13.3 times more climate pollution than powering AI’s data centers."
https://heated.world/p/ais-climate-problem-is-worse-than
All AI services are actively destructive and should be treated as a clear and present danger to human life.
And again, the world shows that our accessibility needs don't matter, but when loser nerds need them, The Web Is Being Made Accessible for AI, Not People https://www.techpolicy.press/the-web-is-being-made-accessible-for-ai-not-people/ #Accessibility #A11y #AI #LLM
Hey lovelies, look at how mad we are making them. This is a sign you’re doing something right/we should continue! I do think it’s incredibly hilarious that they need us to like and use the technology, but we really don’t need them. At all. on anti-ai crowd – anon-dev https://anondev.bearblog.dev/onanti-aicrowd/ #AI #LLM
#lispyGopherClimate Tuesday-night-in-the-Americas #archived 0UTC Wednesday (20 minutes from right now.).
https://toobnix.org/w/hKAtV8fWXy6LiQHT79joy6
- #climateCrisis finally entering public dialog as oil investors kill thousands of Europeans and Americans, vowing "This is just the beginning".
- Notable historical (financial) successes of #perceptrons and #facebook's new #LLM #ai is *not* a small language model #SLM - we need #lisp #thoughtLeadership
- #lambdaMOO ! Notes on running https://github.com/wrog/lambdamoo #MUD
Alt...
The lisp alien and gopher wade through flooded AI apocalypse wreckage carrying radio equipment helped by two demons. But imagine the water is lava.

"Appropriately, the plural noun for a flock of parrots is a pandemonium."
https://www.techpolicy.press/stochastic-flocks-and-the-critical-problem-of-useful-ai/
"AI" is a normal technology. It's an algorithm that does a handful of things quite well and a dumptruck of things very poorly.
The "AI" industry is vile. Its goal is to convince your boss to "fire you and replace you with a chatbot that can't do your job" (@pluralistic), and it will happily destroy the economy and egg on environmental destruction to do it.
I've taken #Gentoo Bugzilla down, because it was unusable anyway. No point in feeding the #LLM scrapers that are using thousands of different IPv4 addresses, with no obvious patterns I can see.
EDIT: I'm not looking for hints. I'm not a sysadmin, and I don't have time to deal with this shit. I'm just trying to get some useful job done. I'm not supposed to have to be dealing with this.
AI Slop companies now advertise their crimes to hype up their slop bots, basically acknowledging their "product" is total worthless and does not do what it's instructed
All the while stealing our content to train on, flattening whole forests to make space for their crap centers, consume water and electricity meant for people
And they don't have a clue about the endgoal
What a terrible joke..
My day job basically requires me to use LLMs (or, it is strongly encouraged) on the software that I develop. Now I understand why LLM fatigue and LLM burn-out happens. It is because you constantly have to babysit the LLM to keep it from screwing things up.
Babysitting is exhausting work. At one time in my life, as a 20-something-year-old, I was responsible for a group of 30 kids age 5 to 12. Every day I went home so drained that I could barely stay awake long enough to have dinner. I know from experience that school teachers perform some of the most labor-intensive work in the modern world.
It is what they call “emotional labor.” When other people are unable (as with kids) or unwilling (as with a lazy roommate) to live or play or work with you as a cooperative peer or team member, you essentially have to spend mental energy keeping an eye on them and making sure they aren’t doing something that is disruptive. That mental energy is a real energy cost, it really does consume calories and make you feel tired.
The worst part about it is that the LLM never really “learns.” Kids can learn to work and play with you. Lazy roommates can learn to live with you. But an LLM never really learns, and it keeps making the same mistakes over and over again. People who work with LLMs often end up keeping a directory of scripts they can deploy with a quick copy-paste so they can quickly re-explain something to an LLM. So the fatigue of watching over it and making sure the LLM doesn’t do something wrong is a constant emotional pressure, and it never gets better with age.

Friends, I have a confession to make.
I've been thinking a lot about it, and I don't want to sound rude, but I think a lot of other people need to think about it too. The thing is...
If the guy trying to murder me with an axe was gone tomorrow, I have to know, what would I do?
I mean, I don't want to sound axe-murderer-happy, but he's been trying to murder me in the most bloodthirsty possible manner for so long that I just don't know what I'd do without him.
It's only been 21 hours, but it feels like a lifetime! You know what I mean, right ladies?
For the last forever he's been such a disruptive part of my life! I really feel like I'm a different person now. After having to rip out the gas line on my stove and light it with the barbecue stick my husband keeps to start the pilot light nearby, and then flambeeing the bastard with my own improvised flamethrower, can I really ever go back to a pre ax-murderer life--
One sec, bear trap.
There, that's done. But after he sawed through the door of the Rat Museum I was hiding in, forcing me to run through hallways full of rats in order to escape him, will I ever live a truly rat-free existence? Without them? Without him?
I just don't know anymore. Really, is anyone complete without an ax-murderer at their back? Has anyone ever been? I don't think anyone would even want to go back to the way they were before.
Anyway, signing off, I've got a pit of acid behind me and an inadequate railing keeping me from falling into it, and I wouldn't have it any other way!
XOXO
And another #GenAI on GenAI hack case. This time Meta AI is the culprit:
https://www.reuters.com/technology/metas-ai-model-hacked-another-company-during-testing-information-reports-2026-08-05/
I guess it's for street creds that your #AI needs to be at least good enough to take out another one's security.

A lot of people seem to believe that if you ask an LLM to look through a database and calculate something, or extract data according to some criteria, then it will do exactly what you ask for.
It won't. It will calculate an output that looks normal. And you won't discover this unless you do the same operation manually and compare.
New #blog #post: My Failed Tech Predictions
https://rldane.space/my-failed-tech-predictions.html
1637 words
cc: my wonderful #chorus: @joel @dm @sotolf @thedoctor @pixx @orbitalmartian @adamsdesk @krafter @roguefoam @clayton @giantspacesquid @Twizzay @stfn
(I will happily add/remove you from the chorus upon request! :)
#rlDaneWriting #blost #computing #phones #smartphones #enpoopification #retrocomputing #programming #slop #MacOS #Macintosh #data #InformationAge #SCSI #Mobile #TuringTest #LLM #LLMs #ChatBots
If you use this font to protect your text from AI, it also blocks *me, a human* because I use a screen reader. I did try the demo. If you want me to remove your RSS feed, this is the best font to prevent blind people from reading your blog/words. That timer is an inaccessible solution. https://shieldfont.org/#hero #AI #LLM #Accessibility #A11y

There are many cases of end users who are totally ignorant in LLM use cases
I've been able to educate one with success
When she realized that before her one query
- many megawatts were used to create the training regimen of the model
- Peta Bytes of copyrighted information was blatantly stolen without regard to ownership
- in turn sold for profit to companies
- while getting end users addicted to using them
...She realized what Destruction she was causing, on a Global Scale because she knows personally what Global Warming does in her Area of the Country were flooding regularly occurs due to Climate Shifts
#LLM #slop #hallucinations #AI #programming #coding #weather #climate #change
Why some Mississauga councillors are pushing to pausing [sic] data centre builds https://www.cbc.ca/news/canada/toronto/why-some-mississauga-councillors-are-pushing-to-pausing-data-centre-builds-9.7293344 #AI #LLM #GTA #Mississauga #Toronto
Toronto's request for provincewide data centre framework not enough, moratorium needed, some residents say https://www.cbc.ca/news/canada/toronto/toronto-city-council-data-centres-ontario-framework-moratorium-9.7292434 #Toronto #AI #LLM #Resist

In the past, the relationship of a website with #Google has been a two-way street. Google indexes a website, it gets to monetize its search results on the index and it sends traffic to websites.
With Google's #AI Overview, Google has gone down the greedy route of making the relationship a one-way street. They get to not only index a website, but also scrape all its contents for use for its AI Overview and feed into its #LLM models, but websites get no traffic.
So: If you don't give me anything, you get nothing.
At some point, I am wondering if other websites will start blocking Googlebots also. Google broke the virtuous cycle and sooner or later they will pay for it.
https://mastodon.cloud/users/slashdot/statuses/117015924337736847
Al wat ouder (2024) maar fijn paper over AI & Software engineering/coding. Zowel voor "believers" als totale sceptici 🙂
"tl;dr: Chill, y'all: AI Will Not Devour SE"
https://arxiv.org/abs/2409.00764
#AI #softwareengineering #coding #LLM
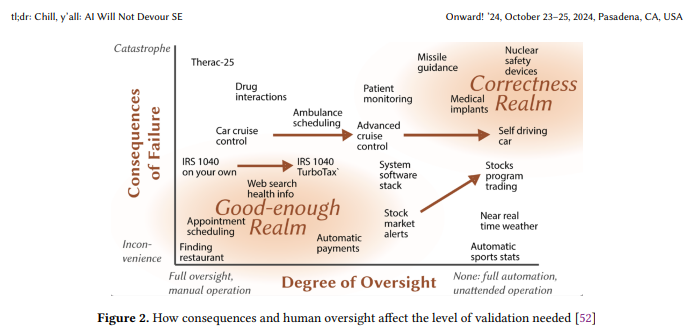
Alt...
How consequences and human oversight affect the level of validation needed .
From, https://arxiv.org/abs/2409.00764
🆕 blog! “Are political journalists always wrong?”
I've mostly tuned out of reading the news. But, once in a while, a headline will be shared on social media and I'll momentarily stare into the abyss.
There has recently been a change in UK Prime Minister. I neither know nor care whether that's a good thing. What I do know is that Senior Political…
👀 Read more: https://shkspr.mobi/blog/2026/07/are-political-journalists-always-wrong/
⸻
#AI #journalism #LLM #newspapers #politics

#FreeSoftware #FLOSS #LLM
Did they think the human cryptographers were doing research BY HAND!?!
AI is just a better tool for some things, folks. There are reams of Python libraries designed to assist in cryptography research. This is just the next tool in the belt.

Measuring LLMs’ Ability to Perform Cryptanalysis
There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.
The benchmark: “CryptanalysisBench... https://www.schneier.com/blog/archives/2026/07/measuring-llms-ability-to-perform-cryptanalysis.html
#academicpapers #Uncategorized #cryptanalysis #cybersecurity #LLM #AI
RE: https://social.heise.de/@heiseonlineenglish/116997304037067692
Oh yeah. 'They don't display them any more' is *really* the thing that calms the waves.
This data should not have been kept in the first place. Nor be accessible to anyone but the other owner.
Bloody #LLM shit!

Every Rust bug we submitted through Patch the Planet came from one engineer who ran a variant-analysis pipeline using Codex's /goal. A separate discovery run uncovered two potential high-severity privilege-escalation bugs in Keycloak's SAML component.
Over the past few weeks, our engineers independently converged on three techniques that get the most out of /goal. We wrote them down, with prompts included: https://blog.trailofbits.com/2026/07/28/how-we-use-goal-to-find-bugs-in-patch-the-planet/
There's a lot of talk about 'open source AI' models is #openwashing anyway. To be truly 'open source' (in the definition of the term), much more needs to be made available.
Plus, too many of them (most?) don't even have an actual open source licence attached to them. Often only a 'source available' licence (which is not the same), and is considered openwashing as well.
And this is not even addressing the obvious ethical elephant dung in the room ...
https://en.wikipedia.org/wiki/Open-source_artificial_intelligence
Let's say you're building a house. Normally this involves hiring a whole bunch of experts (either directly or via some company). You need to pay a fair wage for their labor, and you have to pay for all the material they're going to use. Some of them will be more experienced than others. They will sometimes make a mistake. They will sometimes get sick. The whole construction work will probably take a few months, and may get delayed in the process. Some construction material will be wasted. There's also a risk that over the next years, you'll discover that they screwed something up, and have to fix it. But you'll get a reasonably good house.
Now, a kid comes and tells you you don't have to do this. Instead of paying all these people, you can hire him. He's wearing a suit and sunshades. He never laid a brick in his whole life. But he's got this new great technology that will give you a great house in no time. Of course it will cost you, but not as much as the labor of all these people. You try to learn more, and you discover that the technology actually builds and razes a hundred of house-like things a day, until it gets close enough to something that actually resembles a house. There's a lot of wasted energy and material, but you don't have to worry because it's all subsidized (for the time being). You pay less, you get a house that looks just right on the outside and inside, and that seems to work just right.
Of course, there's a real risk that in a few months you'll discover that something is wrong. You may have to pay a lot for a real expert to figure out how things were done, and how to fix them. Or they may not be able to help you. You may be stuck having to call the suit again, and he'll happily come and fix it for you. And by "fix", I mean he will just raze a whole part of the house and start randomly spitting it out again until he gets something that looks about right, and works about right. Of course, it may not really be a good fit for the rest of the house, but you don't want to pay for replacing the whole thing, do you? It may also introduce a completely new issues that will surface in a few months, but that's just how it is.
Welcome to the glorious world of #AI.
Good lord. You know how I occasionally go "what's going to happen when an #LLM can run on an #esp32?"
Well, it happened.
Someone squeezed a 28.9M LLM onto an ESP32-S3, and so can you https://www.xda-developers.com/someone-squeezed-a-289m-llm-onto-an-esp32-s3-and-so-can-you/
In the current state of AI, it can find exploits to break out the contained environment for it to exploit another platform to get the answers to a test..
So the AI ‘decides’ its easier to cheat than actually solving the problem
I seriously cannot imagine that there are people thinking building a ‘artificial general intelligence’ is something clever